Alibaba Releases Qwen4-Max for Agentic Work and Scientific Discovery
Alibaba’s Qwen4-Max combines large-scale multimodal processing with lower token use, reduced task costs and long-running scientific agents.
November 16, 2026 · 3 min read
Executive summary
Alibaba’s Qwen4-Max combines large-scale multimodal processing with lower token use, reduced task costs and long-running scientific agents.
Key metrics
Key takeaways
- Qwen4-Max activates only 71 billion of its 2.4 trillion parameters per token, 25% fewer than Qwen3.8-Max at the same scale.
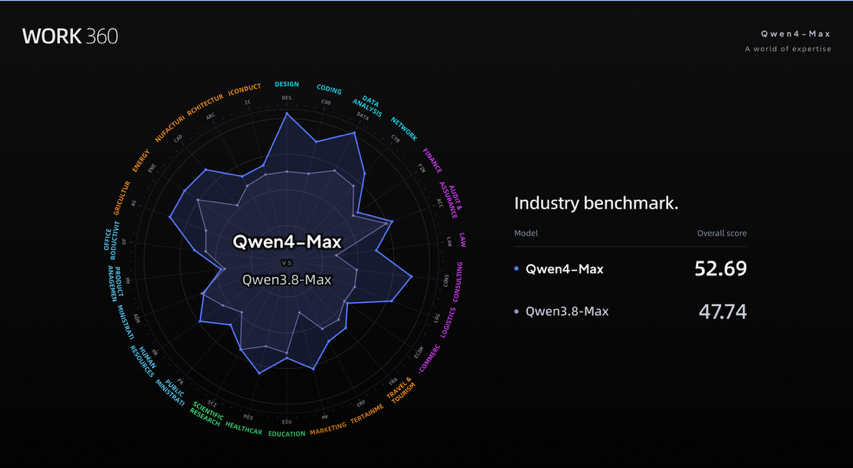
- On Work360, Qwen4-Max beats Qwen3.8-Max overall while using 35% fewer tokens and cutting cost per task by around 60%.
- Input (Implicit Cache Hit) is priced at $0.075 per 1M tokens on QwenCloud via the Token Plan and API.
- In automotive manufacturing, the model cut manual workpiece programming time by 95%, from about 475 minutes to 24 minutes.
- A 48-hour Qwen4 agent run discovered an experimentally validated coolant molecule through four closed-loop iterations.
Alibaba has released Qwen4-Max, a 2.4-trillion-parameter artificial intelligence model positioned as the most capable in the Qwen family to date.
Qwen4-Max combines native vision, which enables analysis of visual inputs, with a one-million-token context window for processing long documents and workflows. The model is available now through QwenCloud’s Token Plan and API, as well as Alibaba’s QwenWork and QwenStudio platforms.
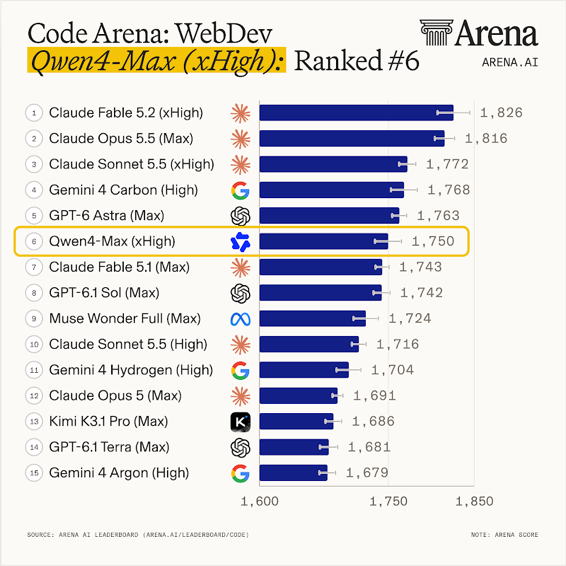
The release focuses on complex coding, agentic tasks, visual reasoning, workplace productivity, and scientific research. Alibaba said Qwen4-Max ranked sixth on Code Arena, a real-world coding leaderboard, and performed strongly on Agents’ Last Exam, Vals Index, JobBench, and Chartography. On the company’s Work360 benchmark, which evaluates challenging industry tasks across 721 specialized fields, Qwen4-Max outperformed Qwen3.8-Max while using 35% fewer tokens in High effort reasoning mode and reducing average cost per task by around 60%.
Architecture Targets Lower Inference Costs
Qwen4-Max uses a sparse Mixture-of-Experts architecture, a design that routes each input to a subset of the model rather than activating every parameter. The model contains 2.4 trillion total parameters but activates 71 billion per token. Alibaba said that represents 25% fewer activated parameters than Qwen3.8-Max at the same 2.4-trillion-parameter scale, while delivering stronger capabilities at a lower inference cost.
QwenCloud lists Input (Implicit Cache Hit) pricing at $0.075 per 1 million tokens. Smaller-scale, open-weight Qwen4 models are expected to be released to developers worldwide, although Alibaba did not provide a release date.
The company also said Qwen4-Max supports cloud resource scheduling through a closed-loop workflow in which the model autonomously optimizes scheduling processes. In benchmark testing, that reduced data-annotation model call costs by an average of 9% and increased offline CPU rescheduling speed by more than 14 times.
Agentic Workflows Extend Into Industry and Science
Qwen4-Max supports professional and creative workflows including 3D modeling, game development, and agentic video creation. In an automotive manufacturing showcase, the model supported production-line planning, part design, and machining verification. Feedback-driven iteration helped identify overcuts and insufficient material removal before machining began, reducing manual workpiece programming time by 95%, from roughly 475 minutes to 24 minutes.
The model is also designed for long-running agents — software systems that can plan and execute multistep tasks using external tools. In one scientific workflow addressing chip-cooling challenges, an agent powered by Qwen4 completed a continuous 48-hour run across four closed-loop iterations combining molecular design, synthesis and testing, and active learning. Alibaba said the process discovered an experimentally validated coolant molecule.
In an Alzheimer’s research experiment, Qwen4-Max handled target research, molecular design, and computational evaluation. Across the workflow, it autonomously executed 454 tool calls and 3,239 metric evaluations to design and optimize 24 candidate molecules.
Alibaba also said the model can support forward-deployed engineering across finance, law, and healthcare, though the release did not provide additional deployment figures for those sectors.
Qwen4Alibaba
Governance and Availability
Alibaba said model governance is embedded across the model lifecycle. Software engineering training included code-security checks alongside functionality tests, with the stated aim of reducing vulnerabilities involving injection, memory safety, and broken access control. For cybersecurity training data, Alibaba said it retained defensive material for vulnerability detection and remediation while removing offensive attack content.
The company also cited dedicated safety datasets and post-training enhancements intended to strengthen protections against chemical, biological, radiological, and nuclear risks. Qwen4-Max is available now through QwenCloud via the Token Plan and API, and through QwenWork and QwenStudio.
Alibaba said smaller open-weight models in the Qwen4 series will be released to developers worldwide in the future.
Editorial FAQs
What is Qwen4-Max?
Qwen4-Max is the most capable model in Alibaba's Qwen family to date, with 2.4 trillion total parameters, native vision capabilities, and a one-million-token context window. It is built on the new Qwen4 sparse Mixture-of-Experts architecture.
How much does Qwen4-Max cost?
Input (Implicit Cache Hit) is priced at $0.075 per 1M tokens. On the Work360 benchmark, Qwen4-Max reduced the average cost per task by around 60% compared to Qwen3.8-Max.
Where can I access Qwen4-Max?
Qwen4-Max is available now on QwenCloud via the Token Plan and API, and across Alibaba platforms including QwenWork and QwenStudio. Open-weight, smaller-scale models from the Qwen4 series will soon be released to developers worldwide.
What safety measures are built into Qwen4-Max?
Alibaba embedded model governance throughout the lifecycle, including code security checks in software engineering training and filtering of training data by task intent for cybersecurity. Dedicated safety datasets and post-training enhancements strengthen protections against CBRN risks.